OmniRoute

OmniRoute

Download OmniRoute free for PC and phone

3069 downloaded
591.4 MB installer size
4 341 reviews
The content of games with a PEGI 3 rating is considered suitable for all age groups. The game should not contain any sounds or pictures that are likely to frighten young children. A very mild form of violence (in a comical context or a childlike setting) is acceptable. No bad language should be heard.

Equivalent to E (low end) and EC (which is no longer used). 435 titles were rated PEGI 3 in 2020. PEGI Rating
Scanned by antivirus. No registration.
Windows 7 / 8 / 10 / 11
Version: 3.8.52

This software connects over 200 AI providers through a single local endpoint, enabling automatic switching when quotas are reached or errors occur. It supports 17 routing strategies, including load balancing and cost prioritization. Built-in request compression cuts token usage by up to 95%, speeding up processing and saving costs. An intuitive interface and integration with 20+ tools ensure smooth, efficient workflows.


  • Download Apps & Games for PC and Android
17 Nov 2026
Title OmniRoute
Version 3.8.52
Size 591.4 MB
Price free of charge
Category Utilities
Developer Diego Rodrigues de Sa e Souza
System Windows

OmniRoute installation

download

Click on the Download button to start downloading OmniRoute for Windows from Maombi.com

open

Open the .exe installation file in the Downloads folder and double click it

props

Follow the instructions in the pop-up window to install OmniRoute on Windows Desktop

run

Now you can open and run OmniRoute on your PC

OmniRoute Features

OmniRoute offers a unified AI gateway connecting 200+ providers through a local endpoint. It automatically switches providers when quotas run out and supports 17 routing strategies to optimize cost and performance. Token compression reduces expenses and speeds up requests, while a user-friendly interface allows flexible integration and configuration.

Unified AI Access

Unified AI Access

Connect to over 200 AI providers via a single local endpoint for streamlined and efficient use.

Seamless Auto-Switching

Seamless Auto-Switching

Automatically switch between providers when quotas are exhausted or errors occur to maintain uninterrupted service.

Diverse Routing Strategies

Diverse Routing Strategies

Choose from 17 routing options considering cost, latency, and load to optimize request handling.

Built-in Token Compression

Built-in Token Compression

Reduce token consumption by 15–95% without sacrificing code quality or structured data accuracy.

Supports 20+ Tools

Supports 20+ Tools

Integrate seamlessly with over 20 tools including Claude Code, Cursor, and Copilot for enhanced productivity.

Customizable Interface

Customizable Interface

Modern, user-friendly interface with extensive settings to tailor the app to your workflow.

OmniRoute overview

  • slide for 1

    01

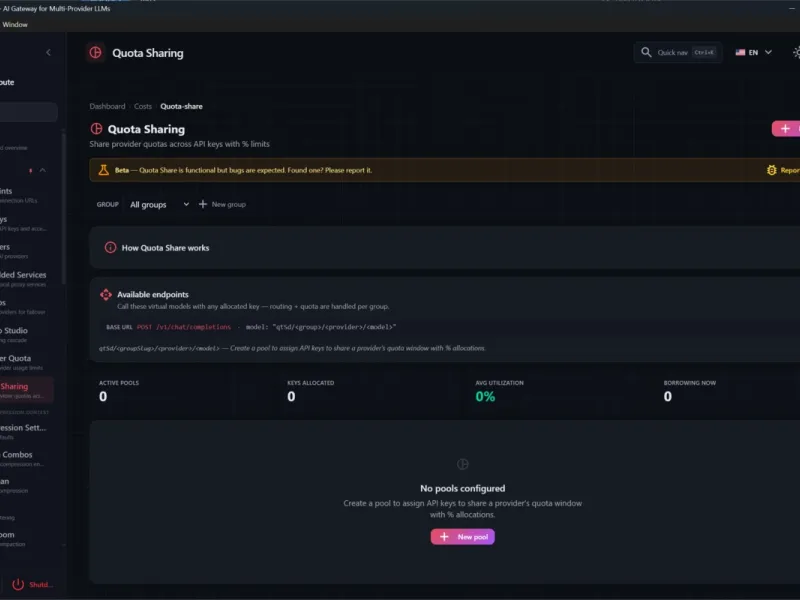
    Divide a service’s total quota among API keys by assigning each a percentage share. Group keys to separate AI model access for different tasks. Counters track the number of pools, allocated keys, and average quota use. A shared request address simplifies working with models by routing and managing limits by group

  • slide for 2

    02

    Access multiple AI services through a single connection. The app smartly routes your requests among them and switches to a backup if one fails, keeping your workflow uninterrupted. Track your spending and token usage easily to stay within budget. Password protection keeps your management controls secure

  • slide for 3

    03

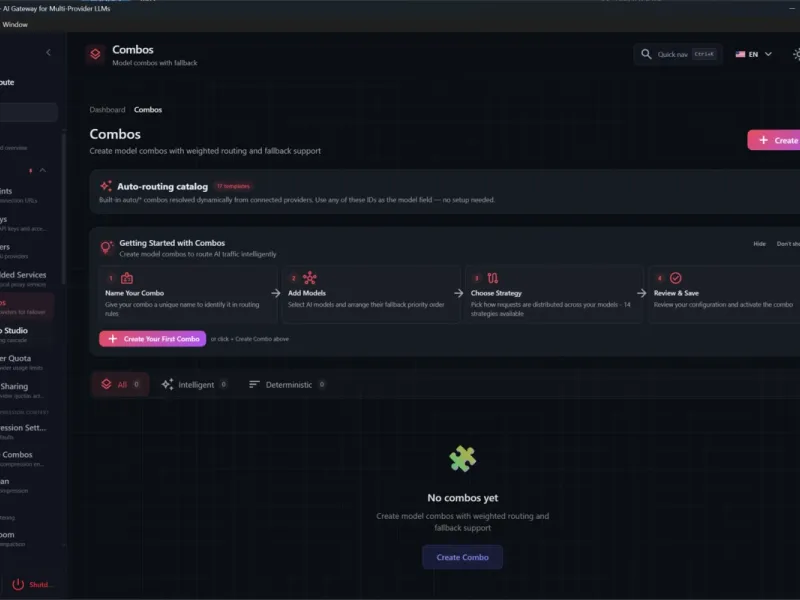
    Group AI models and distribute requests among them. Choose the order to switch to backup models if the main one is unavailable. Adjust the share of requests for each model and select the method for picking them. Ready-made templates help you get started quickly, while step-by-step prompts guide you from naming groups to saving settings

  • slide for 4

    04

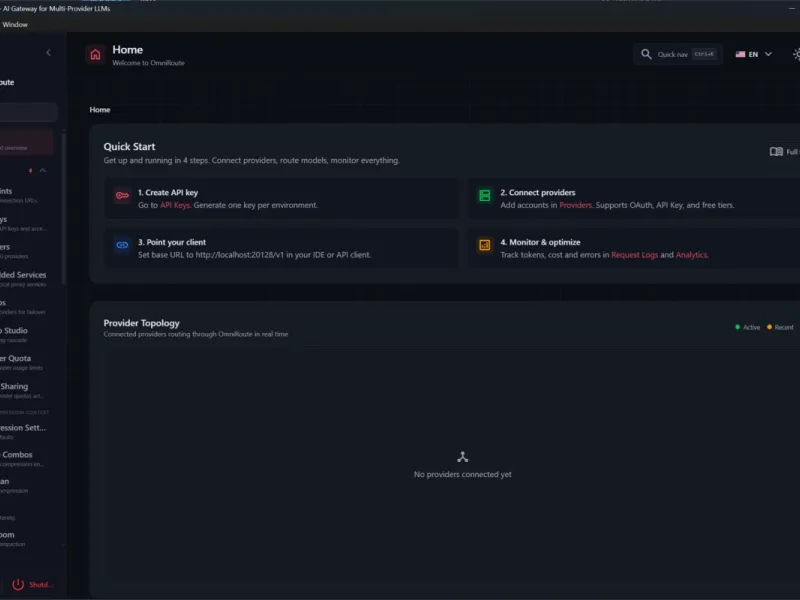
    Connect various neural network services and reach them all via one address from your code editor or other apps. Create separate access keys for different tasks. The app displays connection statuses and helps monitor token use, costs, and request errors. Grouping providers lets you switch seamlessly to backups when needed

  • slide for 5

    05

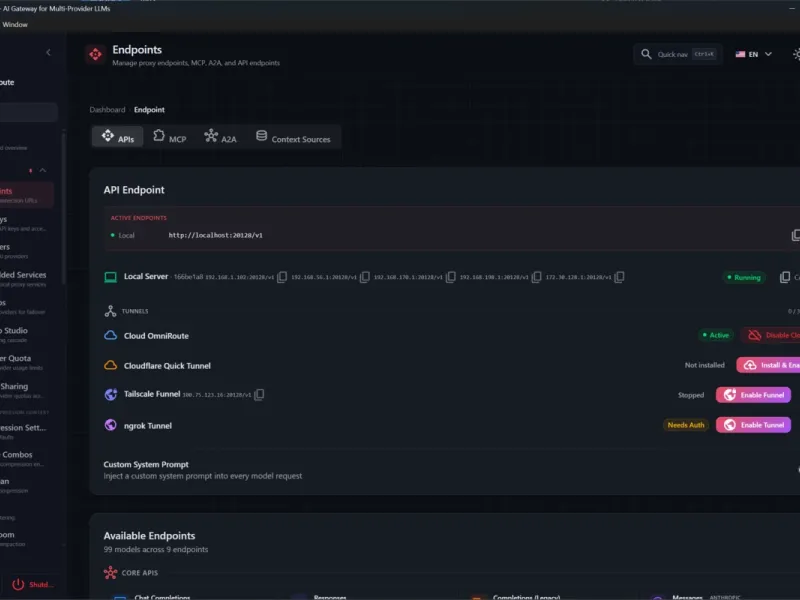
    Link your applications to different AI models through a single request address. The app shows local server addresses for easy copying and use on other devices in your network. Enable cloud connections or tunnels for internet access and check their status. A shared instruction set is added automatically to each request, so you don’t have to repeat it manually

  • slide for 6

    06

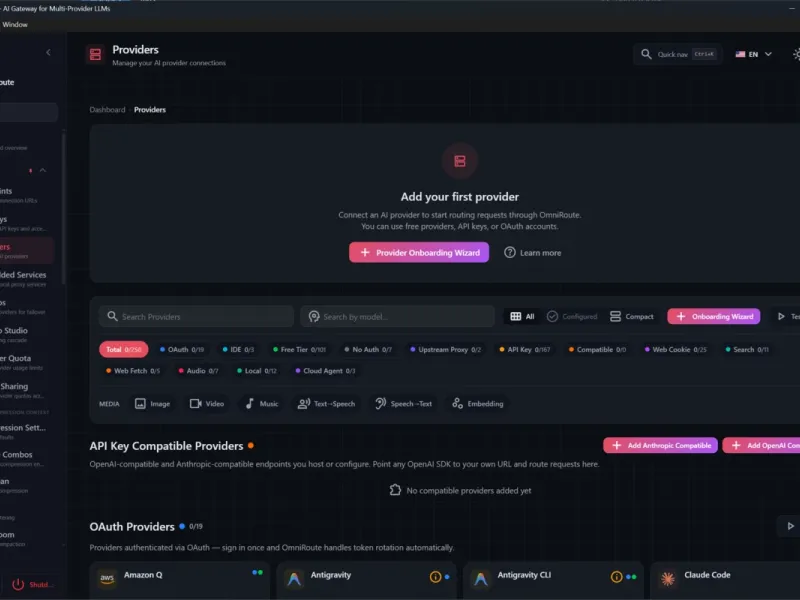
    Route requests through one app by connecting to various AI services. Access them using API keys or account login, with a step-by-step setup to get started quickly. Search services by model and pick features like audio processing, speech recognition, or text-to-speech. Monitor connection availability together to spot issues faster

  • slide for 7

    07

    Chain together multiple AI services to pass requests to backup providers during outages. Monitor these chains live and switch between them smoothly. Keep all access keys and connections organized in one place for easy management. Limit controls help you track how much resource each provider has left

  • slide for 8

    08

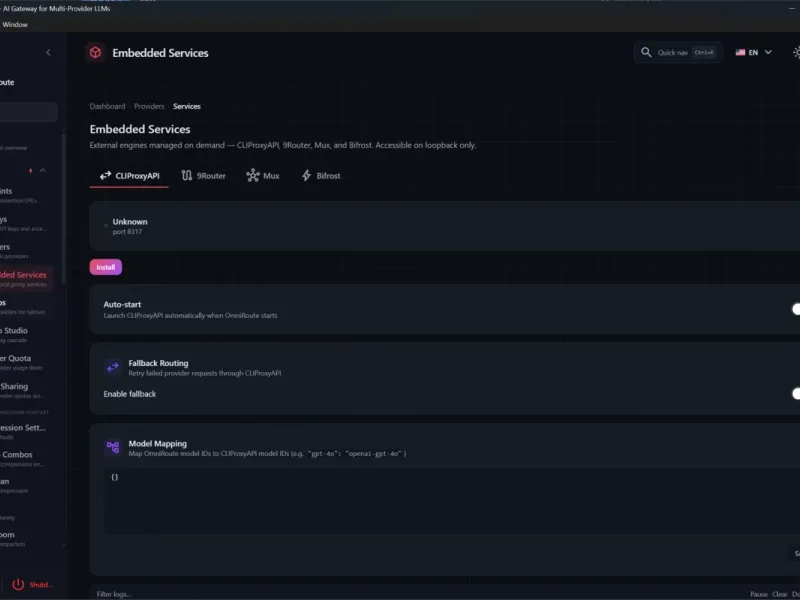
    Add local AI services and set them to start automatically with the program, so you don’t have to launch them manually each time. If a request to a provider fails, the app retries it through an alternate route. Matching model names helps link familiar labels with those recognized by each connected service

  • slide for 9

    09

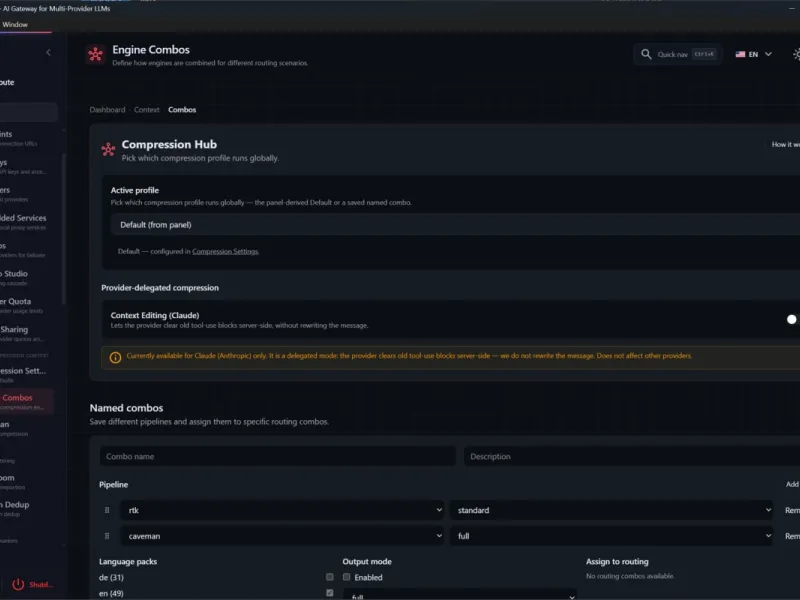
    Build a request processing chain for neural networks: shorten text and filter out excess before sending. Save custom step sets for different tasks and pick a general compression profile. Tailor the order and degree of reduction to your preferences. For supported services, enable automatic cleanup of old tool call data without rewriting messages

  • slide for 10

    10

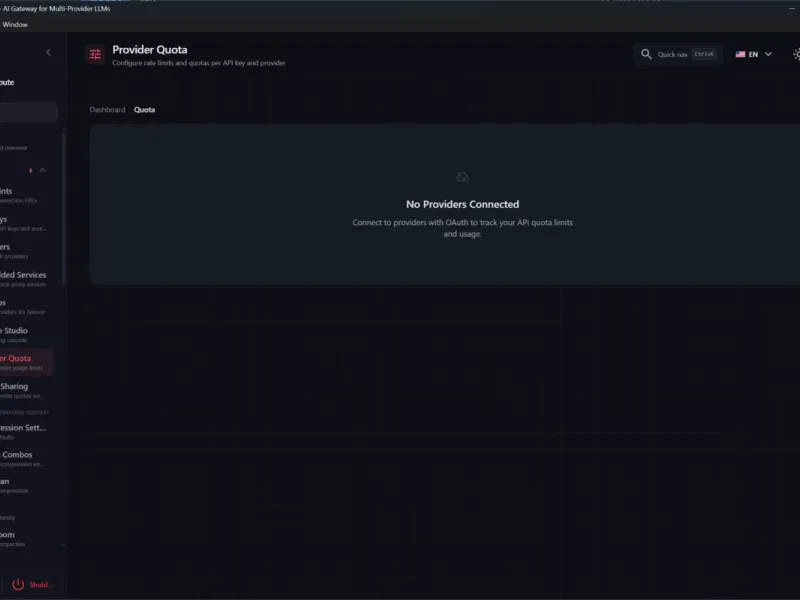
    Connect AI services and keep an eye on your available request usage. Set limits for individual providers and access keys to keep quotas in check. Group connections to switch automatically to backup services if one fails. Usage insights reveal where your request allowances are going

  • slide for 11

    11

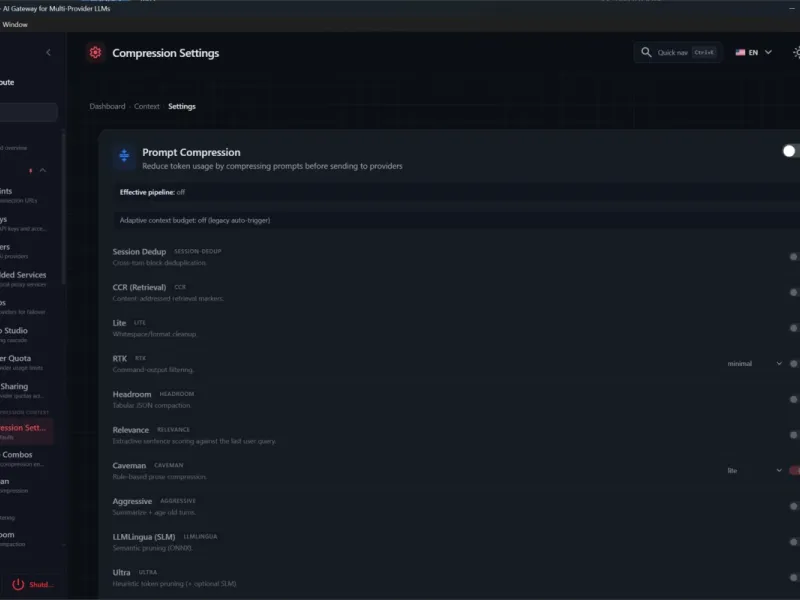
    Reduce token use by trimming requests before sending them to neural networks. The app removes repeated chat fragments, extra spaces, and unnecessary parts of command outputs. Compress long chat histories by keeping only phrases related to the latest question. Enable compression methods individually and adjust their intensity to fit your needs

  • slide for 12

    12

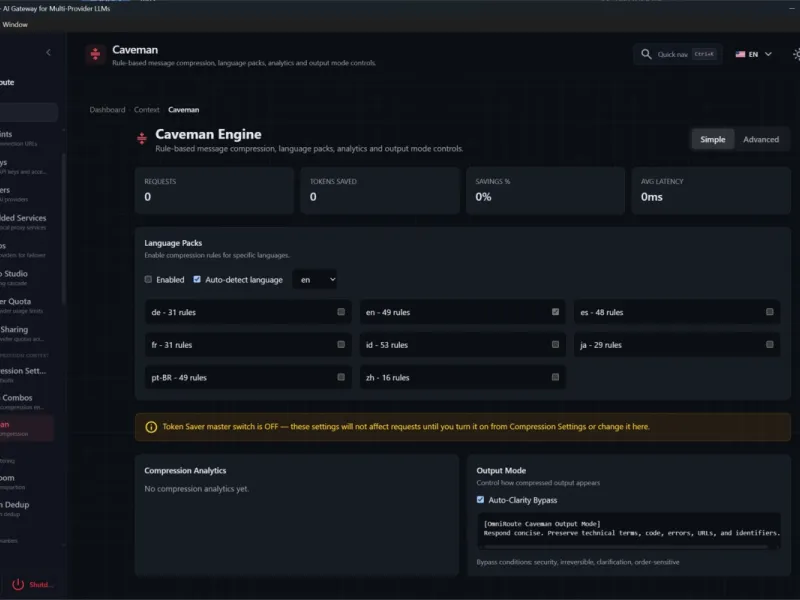
    Shrink messages for language models to save tokens on requests. The app supports compression rules for multiple languages and can detect the language automatically. Track request counts, token savings, and average delays with built-in stats. Choose a concise response style that preserves technical terms, code, links, and error messages

  • slide for 13

    13

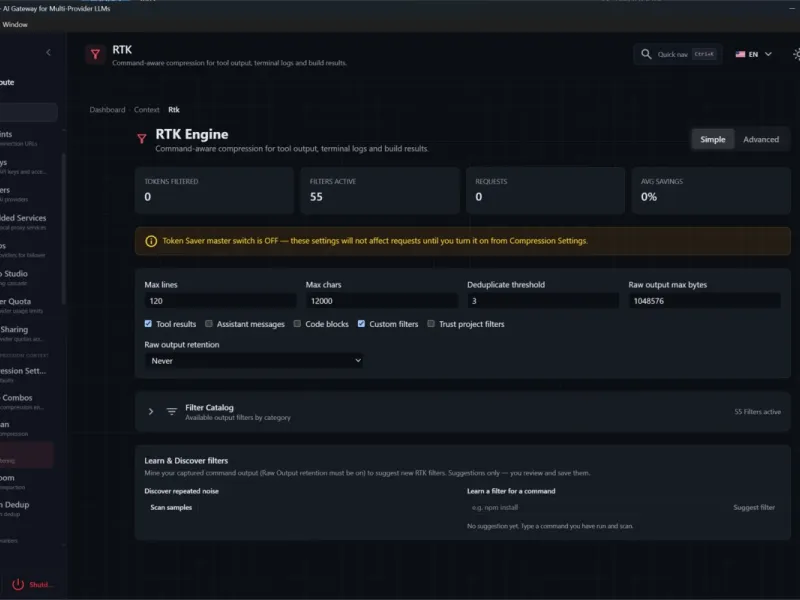
    Compress lengthy command reports and tool results before sending them to neural networks. Set limits on lines and characters, remove duplicates, and select which data to process. Identify noise in saved results and create custom filters based on it. Counters help monitor request numbers and token savings

  • slide for 14

    14

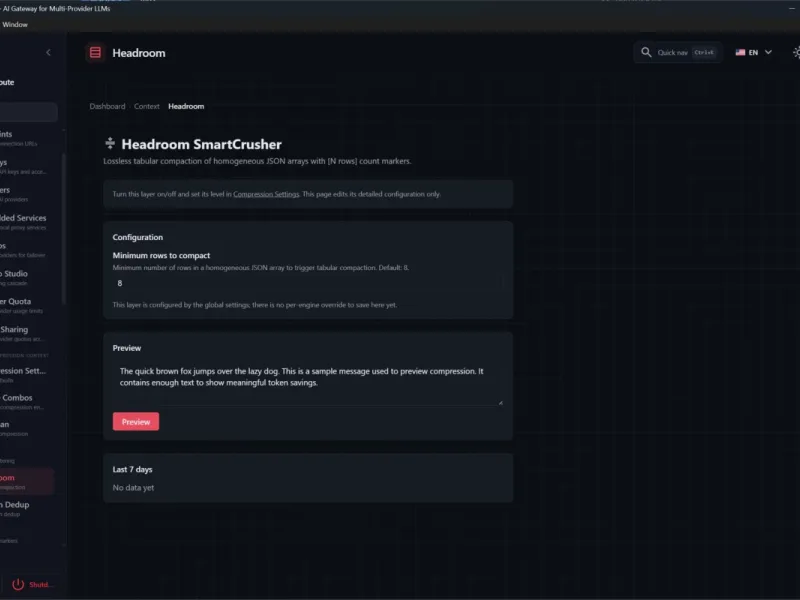
    Pack similar JSON records into tables to reduce data size for language models without losing content. Define how many rows trigger this compression so short lists stay unchanged. Test processing on sample text and evaluate token savings. Seven-day stats keep you informed about results

  • slide for 15

    15

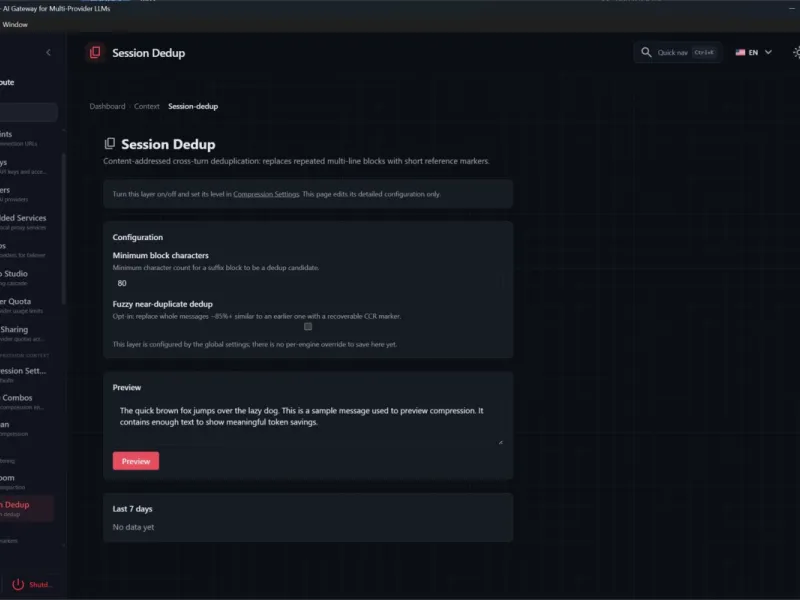
    Cut down repeated chat content so long message fragments don’t take up extra space in requests. The app replaces identical blocks with short links and detects very similar messages. Set the minimum text length for this processing and enable fuzzy matching. Test compression on sample messages before applying your chosen settings

  • slide for 16

    16

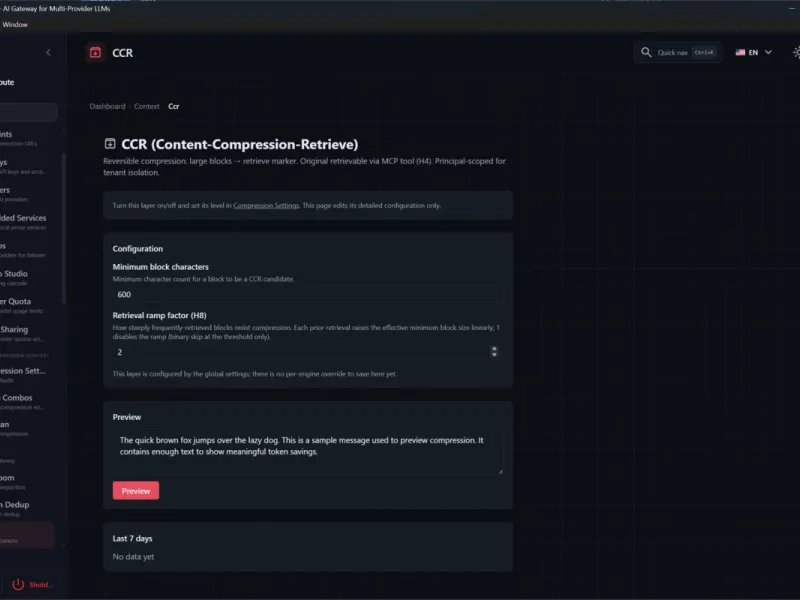
    Shrink long text fragments in AI requests while keeping the option to restore the original content. Set a minimum length for compression and make frequently requested parts less likely to be shortened. Test the process on sample text to gauge token savings. Seven-day stats help you track progress

  • slide for 17

    17

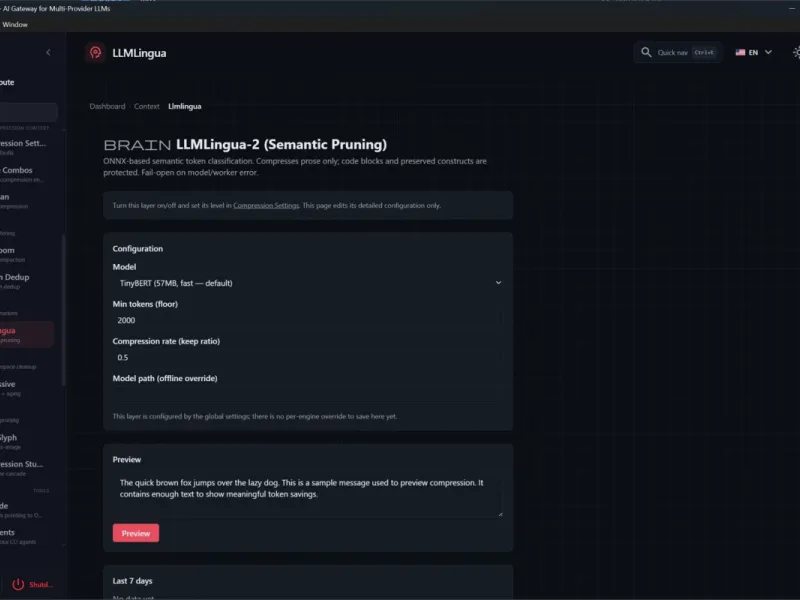
    Trim down neural network request texts by removing unnecessary parts while preserving meaning. The app compresses plain text but leaves code blocks and protected fragments intact. Select the model, set how much text to keep, and choose the threshold for starting compression. Preview results on sample messages to see how many tokens you can save

OmniRoute FAQ

OmniRoute

Download OmniRoute

OmniRoute reviews

No reviews yet

Be the first to review OmniRoute!